Submitted to ICASSP 2027
SPATEX
Array-Flexible Multichannel-to-Multichannel
Target Speech Extraction Using Direction Clue
Audio examples
One model · epoch 85A target direction in, a target speech image at every microphone out.
Choose a microphone to compare the same excerpt. Playback stays aligned within each row.
Loading audio examples…
6-second excerpts · 8 kHz · Shared gain across signals and microphones in each scene.
The idea
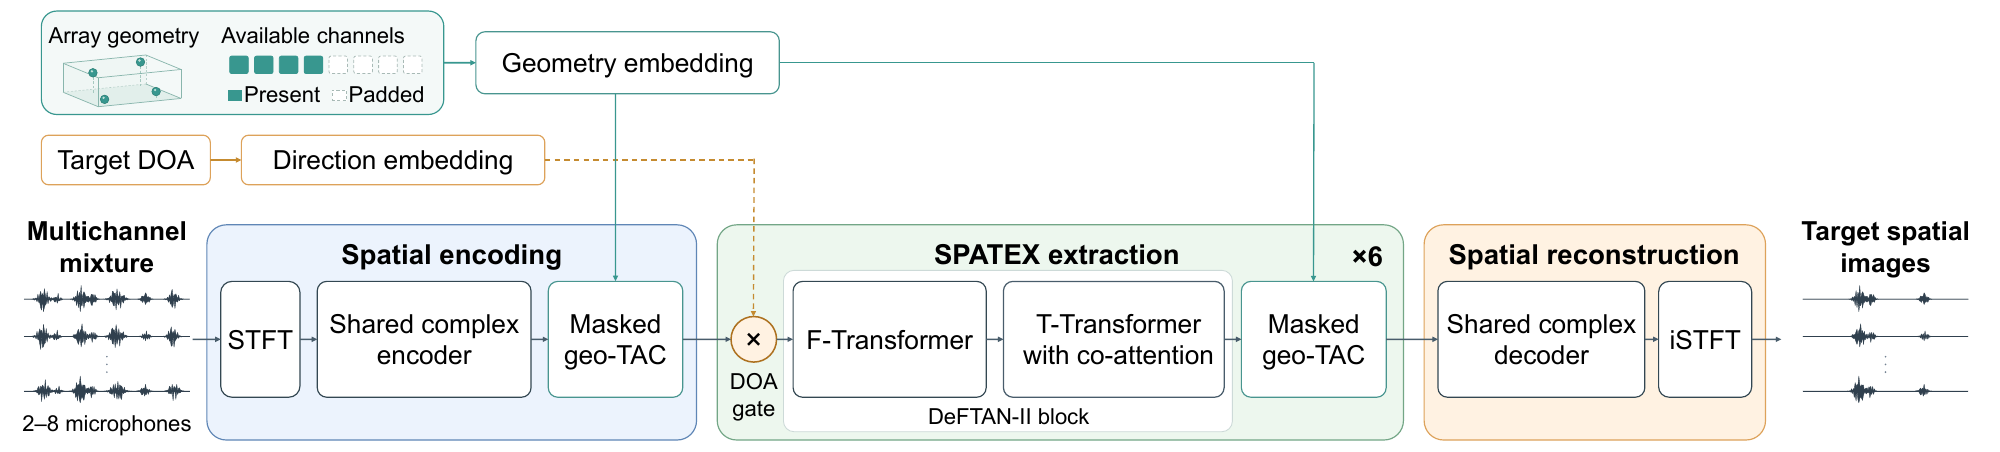
Reproduce SPATEXSPATEX uses microphone coordinates and a target direction to extract speech across different arrays. Geometry-aware channel exchange and shared temporal attention connect microphone streams, while IPD and coherence losses preserve their spatial relationships. The same model reconstructs a separate target image for every microphone.
About these examples
All three examples use the released variable-array epoch-85 checkpoint, trained with 2–8 microphones. Fixed and matched examples use linear and planar layouts; the unmatched example uses a random layout with 1 cm microphone-position perturbations. Speech comes from LibriSpeech test-clean with simulated room responses.
Examples are the first saved scenes matching each geometry and microphone count, without selection by output score. Playback uses one common attenuation gain per scene. Waveforms and spectrograms share scales across signals and microphones. Downloads retain the original floating-point multichannel output.
Metrics in the expanded rows describe individual six-second examples, rather than the paper’s two-second benchmark averages. Generation details · Sample provenance
Citation
@unpublished{wen2026spatex,
  title  = {{SPATEX}: Array-Flexible Multichannel-to-Multichannel
            Target Speech Extraction Using Direction Clue},
  author = {Wen, Wen and Chen, Changda and Xi, Yu and Li, Haoyu
            and Zhou, Qiang and Chen, Guanyu and Gu, Xiaoyu
            and Li, Bohan and Wang, Shuai and Yu, Kai},
  year   = {2026},
  note   = {Submitted to ICASSP 2027},
  url    = {https://github.com/Wenanzhi/SPATEX}
}